NEWS
Google’s Gemini TTS Clones Voices and Then Watermarks Them
Google’s Gemini 3.8 Flash TTS copies a voice from a short clip after spoken consent, watermarks the audio.

Google put Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS on the Gemini API on September 23, 2026. Both models copy a speaker from a short clip, then tag the audio so a detector can still tell it was made by a machine.
Group product manager Leland Rechis and Alan Cowen, director of research science for the Gemini Audio team, said the pair turns “static presets into a dynamic creative studio.” The clone is the product people will try first. The spoken yes, the watermark, and the Hume score Cowen’s old lab still publishes are the rest of the launch.
Google Splits Speech Into a Studio Model and a Workhorse
The two SKUs share one request format, so a developer changes a single model name to move a job from the cheap line to the studio line. Flash TTS is the quality SKU, aimed at audiobooks, games, podcasts, and two-speaker scenes. Flash-Lite TTS is the volume SKU, aimed at dubbing, read-aloud features, and voice agents.
Flash TTS speaks 130 languages with automatic detection. Flash-Lite TTS speaks 101 languages. Both draw on more than 2,000 production-ready voices, up from a set of 30, including regional cuts such as Mexican Spanish, Quebec French, and Scots English. You can also describe a new voice in plain language, then save it.
Flash TTS is live in Gemini Notebook. Flash-Lite TTS is live in Google Vids. Both are in the Gemini API and Google AI Studio now, with a Gemini Enterprise API listed as coming soon. Rechis and Cowen introduced two new text-to-speech models as part of a wider Gemini Audio stack that already includes live translation, transcription, and the 3.8 Live models.
FLASH TTS VERSUS FLASH-LITE TTS
| Spec | Gemini 3.8 Flash TTS | Gemini 3.8 Flash-Lite TTS |
|---|---|---|
| Languages | 130 | 101 |
| Audio price through December 31, 2026 | $9.00 per 1M tokens | $6.00 per 1M tokens |
| Audio price from January 1, 2027 | $18.00 per 1M tokens | $12.00 per 1M tokens |
| Voice Arena Elo | 1,260 | 1,235 |
| Stated job | Audiobooks, studio narration, dialects | Agents, dubbing, high-volume read-aloud |
| Consumer seat | Gemini Notebook | Google Vids |
Line-level direction is on both models. A script can carry stage notes plus non-speech beats written as tags such as laughs, sigh, gasp, mhm, and yeah. Google also says a single script can stage two speakers without mixing the voices, and that timbre holds across long files with less drift than Gemini 3.1 Flash TTS.
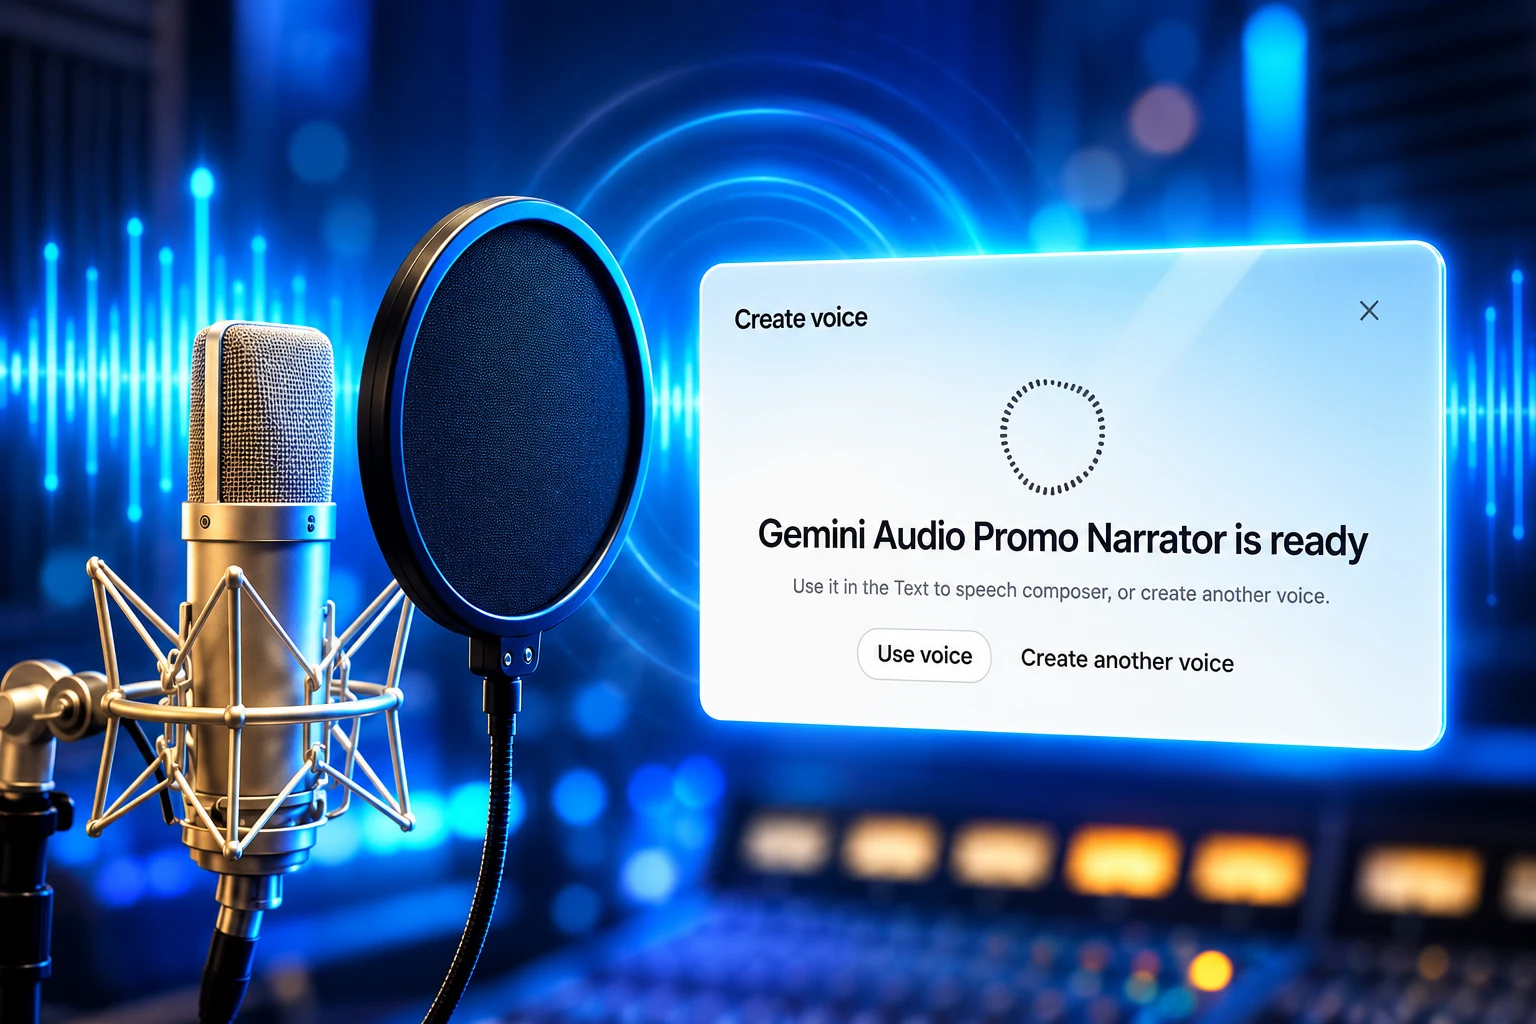
How Gemini Checks Consent Before It Clones a Voice
Voice replication is on both models. The API does not take one file and mint a speaker. It wants two recordings from the same adult, and the second one has to be a legal sentence said out loud.
The reference clip is 10 to 30 seconds of clean speech. The consent clip must match that speaker and recite Google’s required line. A clone built from a scraped video, or from audio that an image model already invented, fails that check because the speaker is not there to say yes.
I am the owner of this voice and I consent to Google using this voice to create a synthetic voice model.
Mandatory English consent line, Gemini API voice replication docs
That mandatory consent statement is the brake on the feature. People who tried their own voices on September 24 said the copy sounded close, and that the acting cues were strong enough to carry a non-actor’s sample. They also said the second clip had to be their own spoken permission. That is the point of the design: the model can copy you, and it will not start until you read the sentence.
WHAT A CREATEVOICE REQUEST MUST INCLUDE
- Two adult clips: Reference speech of 10 to 30 seconds, plus a matching consent recording from the same speaker.
- The legal line: The speaker must recite Google’s consent sentence in a supported locale, not a paraphrase.
- A stored ID or a key: Stateful voices persist in the project; stateless keys stay on the client.
- A watermark on output: Every Gemini Audio clip carries SynthID, and replicated voices also get C2PA credentials.
Every clip from the Gemini Audio models carries an imperceptible SynthID watermark woven into the waveform. Humans are not supposed to hear it. Detection tools are. Google frames that tag, plus the consent step, as protection for voice talent as much as for the company.
Google AI Studio is the interactive path: record or upload both clips, preview the speaker, then copy a voice_ ID into code.
introducing Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, our most expressive audio generation models yet
these models enable creators, developers, and enterprises to create richer, more expressive audio experiences
try them via the Gemini API and in AI Studio:… pic.twitter.com/vV84ErmKY1
— Google AI Studio (@GoogleAIStudio) September 23, 2026
The Rank Google Cites Comes From Hume
The launch post puts Flash TTS first on Hume AI’s Voice Design Benchmark at 71.4, and first on accent modeling at 60.8. Flash TTS and Flash-Lite TTS also take first and second on Hume’s Overall Quality Index. Those figures are Google citing Hume, not a separate audit of Hume’s sheet.
Cowen founded Hume AI, the New York lab known for emotion-tagged voice models. On January 24, 2026, he wrote that he had joined Google DeepMind and was no longer at Hume. His byline on the September 23 post is director of research science, on behalf of the Gemini Audio team. Hume still sells its own speech models. On the public listening board below, Hume’s Octave 2 sits at Elo 1,049, far under Google’s new pair.
These models enable creators, developers, and enterprises to create richer, more expressive audio experiences, while enabling improved user experiences in products like Gemini Notebook and Google Vids.
Leland Rechis, Group Product Manager, and Alan Cowen, Director, Research Science, Google blog
None of that makes the Hume numbers false. It does mean the scoreboard Google chose shares a founder with the team that just shipped the models. Blind listener tests that Google does not run tell a tighter story.
Cartesia Still Leads the Public Listening Test
Artificial Analysis ranks TTS models with an Elo score from blind votes on its Provider Voice Arena leaderboard. Listeners hear two clips of the same text and pick the more natural one. Cartesia’s Sonic 3.6 is first at Elo 1,273. Gemini 3.8 Flash TTS is second at 1,260. Alibaba’s Qwen-Audio-3.0-TTS-Plus is third at 1,259.
PROVIDER VOICE ARENA, TOP OF THE BOARD
| Model | Elo | Rank band | Samples |
|---|---|---|---|
| Cartesia Sonic 3.6 | 1,273 | 1-3 | 1,757 |
| Gemini 3.8 Flash TTS | 1,260 | 1-4 | 1,999 |
| Qwen-Audio-3.0-TTS-Plus | 1,259 | 1-4 | 1,447 |
| Inworld Realtime TTS-2 | 1,245 | 2-7 | 1,239 |
| SpeechifyAI Simba 3.2 | 1,237 | 4-7 | 2,391 |
| Gemini 3.8 Flash-Lite TTS | 1,235 | 4-7 | 2,000 |
The 13-point gap from Cartesia to Flash TTS sits inside both models’ ±17 intervals, so the board’s own range column still allows a 1-4 finish for Google. Flash-Lite TTS is sixth at 1,235. The preview these SKUs replace, Gemini 3.1 Flash TTS, is tenth at 1,199 on 3,430 samples. ElevenLabs’ v3 Conversational model is twelfth at 1,196.
Google’s own Voice Arena claim is narrower than overall Elo. The blog says Flash and Flash-Lite took top spots in Japanese, Brazilian Portuguese, Vietnamese, Modern Standard Arabic, Mexican Spanish, and Hindi. That is a language-by-language result, not the all-accent table above. On Google’s announcement thread, a lot of developers skipped the clips and asked for Gemini 4 Pro instead, which is a fair read of where TTS now sits: expected, not the model people showed up to argue about.
Flash TTS Audio Is $9.00 per Million Tokens
Paid Gemini Developer API pricing bills text in and audio out. Flash TTS is $0.50 per million text tokens and $9.00 per million audio tokens through December 31, 2026, then $1.00 and $18.00 from January 1, 2027. Flash-Lite TTS is $0.50 and $6.00 through December 31, then $1.00 and $12.00. Audio is metered at 25 tokens per second, which is 90,000 tokens for one hour of speech.
ONE HOUR OF SPEECH AT LIST RATES
- Flash now: $0.81 per hour of audio at the $9.00 intro rate.
- Flash-Lite now: $0.54 per hour at the $6.00 intro rate.
- Flash in 2027: $1.62 per hour after the rate doubles on January 1.
- 3.1 preview: $1.80 per hour at the $20.00 audio rate the new pair replaces.
The intro window undercuts the preview it replaces, then the January 1 step doubles the audio line. Free-tier audio is billed at $0 and may be used to improve Google’s products. Paid-tier audio is not. Developer platforms already wiring the models in include Agora, LiveKit, Pipecat, and Vercel. Google also named Figma, HeyGen, Linguana, Wondercraft, 99.co, and Ollang as design partners for dubbing, localized accents, and agents.
Voice Replication Stops at the State Line
A footnote on the launch post is more specific than the API docs. Voice replication through AI Studio is not available in Illinois, Texas, the EEA, the United Kingdom, Switzerland, and India. Google did not spell out the legal trigger in that note. Anyone shipping a clone feature has to treat those markets as dark until the company says otherwise.
WHERE THE STUDIO CLONE DOES NOT RUN
- U.S. states: Illinois and Texas are carved out of AI Studio replication.
- Europe and the UK: The EEA, the United Kingdom, and Switzerland are on the same list.
- India: Also blocked for AI Studio replication, with no extra detail in the footnote.
A third customization path, remixing a library voice by prompt (add a Southern U.S. accent, soften the delivery), is listed as coming soon. The Gemini Enterprise API is not live. The public API and AI Studio already take the two clips, stamp SynthID on the output, and charge the intro audio rate until December 31, 2026.
Frequently Asked Questions
Can Gemini 3.8 Flash TTS Clone a Voice From a Short Clip?
Yes, on both Gemini 3.8 Flash TTS and Flash-Lite TTS, if you send a 10 to 30 second reference clip and a matching consent clip from the same adult speaker. Google recommends 24kHz mono 16-bit WAV. Stateful clones share a cap of 200 stored voices per project and last one year; a store=False request returns a client-held key that lasts seven days.
What Consent Phrase Does Google Require for Voice Replication?
In English (US or UK) the speaker must say, “I am the owner of this voice and I consent to Google using this voice to create a synthetic voice model.” The docs list that line in 30 language locales, and the consent audio has to match the reference speaker. A paraphrase, a different person, or a clip pulled from generated media does not satisfy the check.
Does Gemini 3.8 TTS Add a Watermark to Generated Speech?
Yes. Google says every Gemini Audio clip carries SynthID, an inaudible mark baked into the waveform so detection tools can flag synthetic speech. Replicated voices also receive C2PA content credentials. The Gemini 3.8 Audio model card is the page Google points to for the rest of the safety write-up.
What Is the Difference Between Gemini 3.8 Flash TTS and Flash-Lite TTS?
They share the same API schema, so you switch them with one model ID, gemini-3.8-flash-tts or gemini-3.8-flash-lite-tts. Flash-Lite TTS is the replacement for gemini-3.1-flash-tts-preview on high-volume jobs. Flash TTS is the higher-fidelity line, with 29 extra languages and the $9.00 intro audio rate instead of $6.00. Unary responses now default to WAV with a RIFF header, not the raw PCM that the 3.1 preview returned.

A CubeSat Will Age Whisky That Never Comes Home

A Charity Quote Cost Shia LaBeouf the FKA twigs NDA

Looker Turned a Model’s Body Into Ad Inventory

Infinity Ward Bets a Paid DMZ Will Stick This Time

Disney Sidesteps a Kimmel Renewal as Failla Cites Losses

How to Get Pre Boarding on Southwest – Skip the Line with These Tricks

False AI Intel Nearly Put US Crews on a Chinese Ship

Tim Cook’s $4.6 Trillion Apple Still Runs on One Phone

OpenAI Posts a Navier-Stokes Proof Clay Has Not Touched

Dunes Air Sues Nora Fatehi Over Its Luxury Jet
-
 TRAVEL3 years ago
How to Get Pre Boarding on Southwest – Skip the Line with These Tricks
-
 NEWS1 month ago
False AI Intel Nearly Put US Crews on a Chinese Ship
-
 BUSINESS2 months ago
Tim Cook’s $4.6 Trillion Apple Still Runs on One Phone
-
 NEWS2 months ago
OpenAI Posts a Navier-Stokes Proof Clay Has Not Touched
-
 ENTERTAINMENT2 months ago
Dunes Air Sues Nora Fatehi Over Its Luxury Jet
-
 LIFESTYLE3 years ago
How Often Do You Have to Change a Monkey’s Diaper? The Truth About Pet Monkeys
-
 NEWS2 months ago
Australia Treats Cloud Software Payments as Taxable Royalties
-

 LIFESTYLE3 years ago
How Long Does It Take for Armpit Hair to Grow? The Stages of Hair Growth and How to Shave It